Three places it beat Opus 4.8
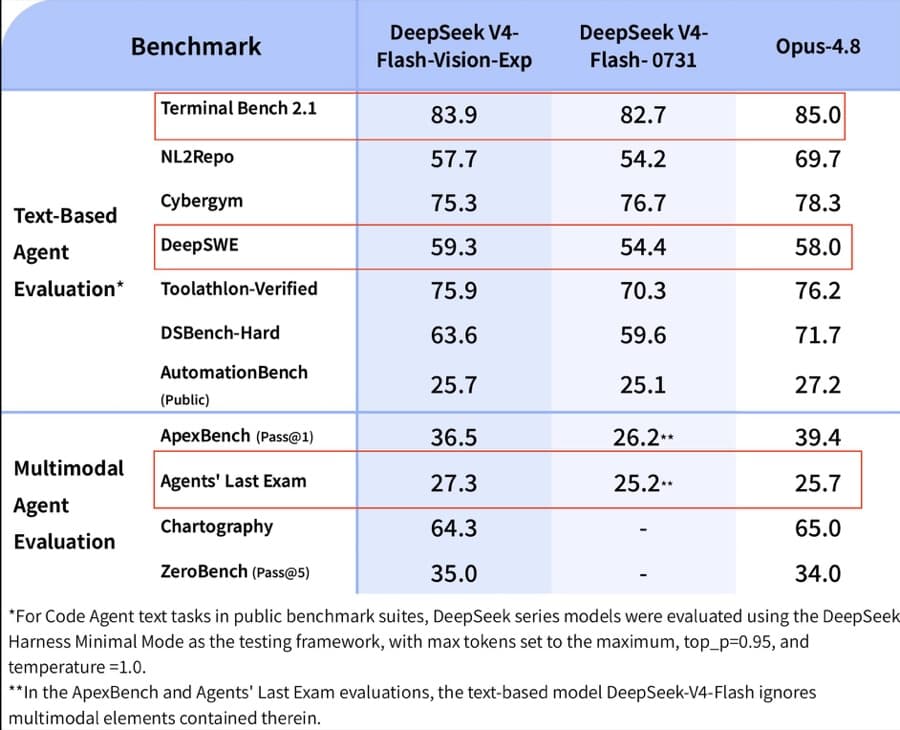
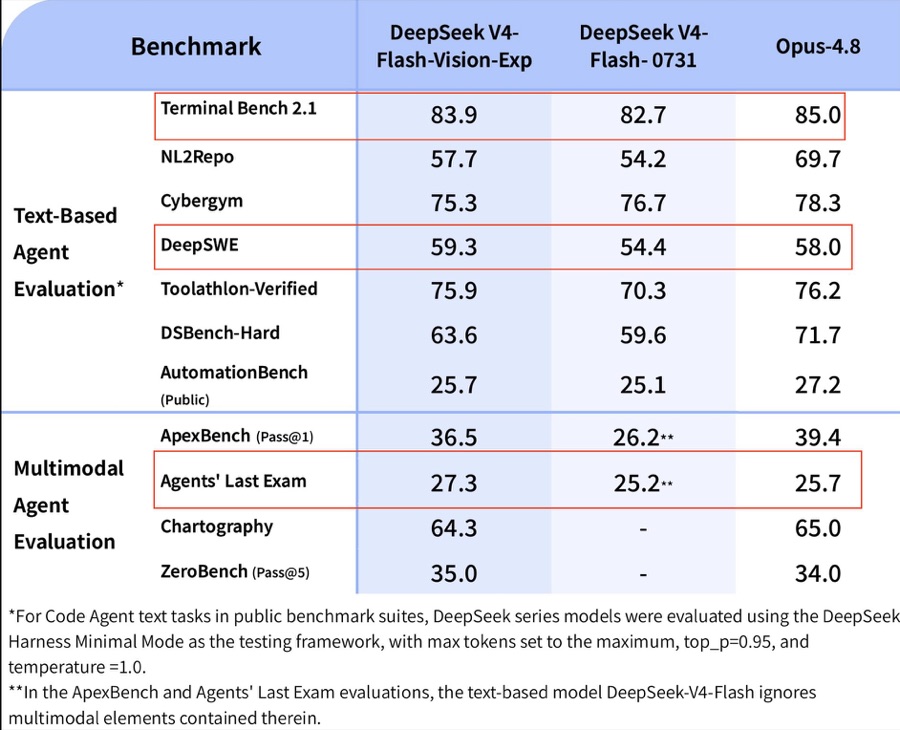
DeepSeek announced via its official X account on August 21 that it had released the experimental multimodal model DeepSeek-V4-Flash-Vision-Exp on the DeepSeek API platform. The benchmark table published in the official API docs shows that the model scored 59.3 on DeepSWE, a coding and agent evaluation, narrowly ahead of Anthropic's Opus-4.8 (58.0). It also scored higher than Opus-4.8 on the multimodal evaluation Agents' Last Exam (27.3 vs. 25.7) and on ZeroBench Pass@5 (35.0 vs. 34.0).
It didn't lead across the board, though. In the same table, NL2Repo is 57.7, 12 points behind Opus-4.8 (69.7), and DSBench-Hard is 63.6, 8.1 points behind Opus-4.8 (71.7). With narrow leads on just three items, it's too early to call it "Opus-class." It's more accurate to say it has reached a level on par with large models on certain multimodal agent tasks.
Text performance is unchanged
DeepSeek says V4-Flash-Vision-Exp is on par with the existing V4-Flash-0731 on text abilities, including agents, reasoning, and world knowledge. That means this update adds the ability to read images and screens without cutting text performance. In fact, on the text-based items in the table (Terminal Bench 2.1, Cybergym, Toolathlon-Verified, and others), the score gap between the two models is mostly within 1 to 5 points.
If you already use V4-Flash for text-only workflows, there's no particular reason to switch now. The Vision version matters for agent tasks that also handle image-based input such as screenshots, tables, and charts.
It plugs in with no price increase
The new model can be called right away under the name deepseek-v4-flash-vision-exp through the Chat Completions, Messages, and Responses APIs, and images can be passed in three ways: base64, an external URL, or the Files API. DeepSeek says adding image input carries the same per-token price as the existing V4-Flash, with no separate price increase. DeepSeek Harness 0.1.1, released the same day, supports the new model by default, so you can try it with no extra setup.