At 12:32 a.m. KST on August 13, 2026, xAI released Grok 4.6 through its official account @SpaceXAI.
The announcement was short.
"Delivers frontier-level intelligence, with meaningful improvements at the same price as Grok 4.5."
Elon Musk reacted directly nine minutes later by quoting the post.
"Grok 4.6 is out. It's smart, fast, and great value." (original post)
Musk's post passed 5.64 million views. The original announcement recorded 18.56 million views.
The Price Stayed Put; Only the Leaderboard Moved
The point of this release is not new features but the price freeze.
Grok 4.6's API price is the same as Grok 4.5: $2 per million input tokens and $6 per million output tokens. When a prompt exceeds 200,000 tokens, it rises to $4 for input, $1 for cached input, and $12 for output. (Compiled by Kingy.ai and Digital Applied)
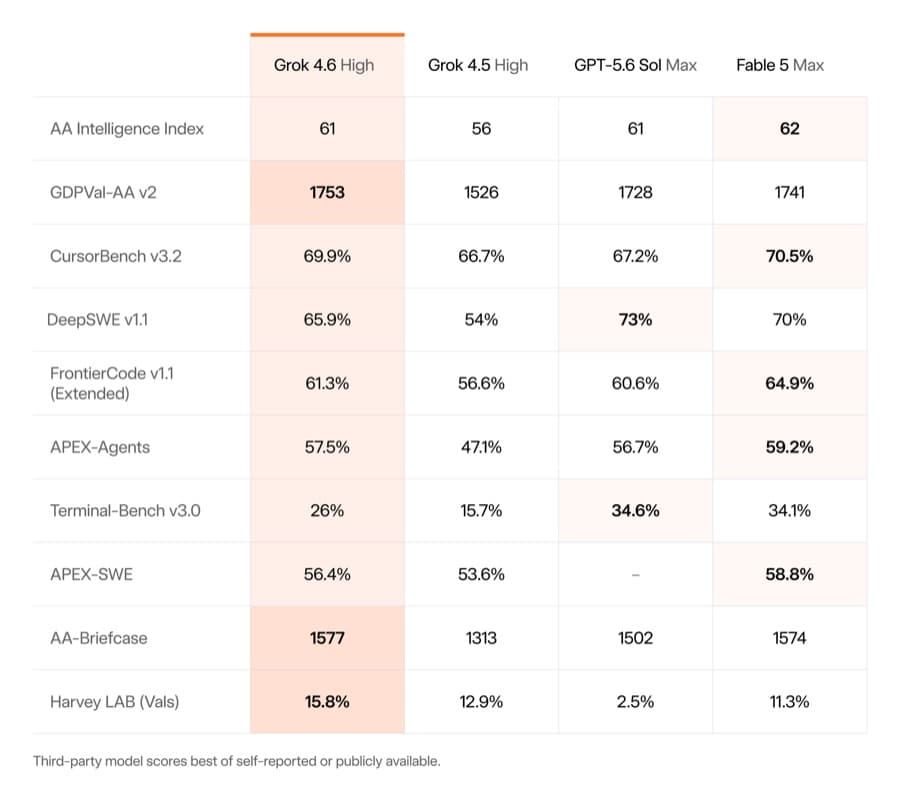
In other words, performance went up at the same price. In the comparison table xAI attached to its official announcement, Grok 4.6 scored 61 on the Artificial Analysis Intelligence Index (AA Intelligence Index). That is 5 points higher than Grok 4.5 (56) and ties GPT-5.6 Sol Max (61). Fable 5 Max still holds a slight lead at 62.
| Benchmark | Grok 4.6 High | Grok 4.5 High | GPT-5.6 Sol Max | Fable 5 Max |
|---|---|---|---|---|
| AA Intelligence Index | 61 | 56 | 61 | 62 |
| DeepSWE v1.1 (software engineering) | 65.9% | 54% | 73% | 70% |
| CursorBench v3.2 | 69.9% | 66.7% | 67.2% | 70.5% |
| Terminal-Bench v3.0 | 26% | 15.7% | 34.6% | 34.1% |
Source: image attached to xAI's official announcement (@SpaceXAI, 2026-08-13 00:32 KST)
Agent and Coding Gains Are Mixed
DeepSWE (a software engineering benchmark) jumped from Grok 4.5's 54% to 65.9%, nearly 12 percentage points. That is the improvement most directly felt in real-world coding agent work.
But GPT-5.6 Sol Max (73%) and Fable 5 Max (70%) are still ahead on the same benchmark. On Terminal-Bench v3.0, Grok 4.6 scores 26%, short of the competing models (in the 34% range).
So this is less "first across the board" and closer to "equivalent performance for less." It is available right away on the xAI API, Grok Build, Cursor, OpenRouter, Vercel, Cloudflare, and more, with a 500,000-token context window. (Kingy.ai)
Grok 4.6 Numbers Are xAI's Own
xAI again did not publish a separate technical blog or model card. The announcement was just an X post and the attached comparison table, and the benchmark figures in this post are based on what xAI itself released.
Some in the community said you get "Fable 5-level performance much cheaper," but that is a claim from an individual account and has not been independently verified. The actual cost savings can vary with prompt length and cache hit rate.
The follow-up model, Grok 4.7, has been teased for "within a few weeks." The thing to watch is whether this price freeze carries over into the next round.