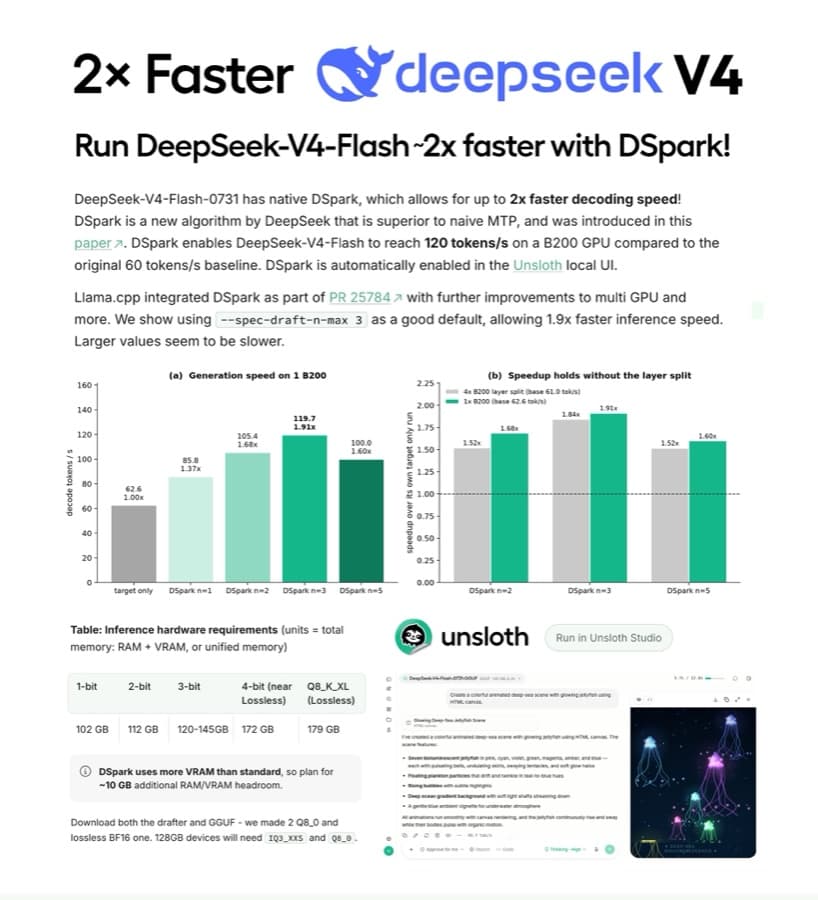
Unsloth, a tool for optimizing local AI inference, has applied DSpark to DeepSeek-V4-Flash-0731 GGUF. The result is 1.4x to 2x faster local inference, so you can run the open model faster with no accuracy loss.
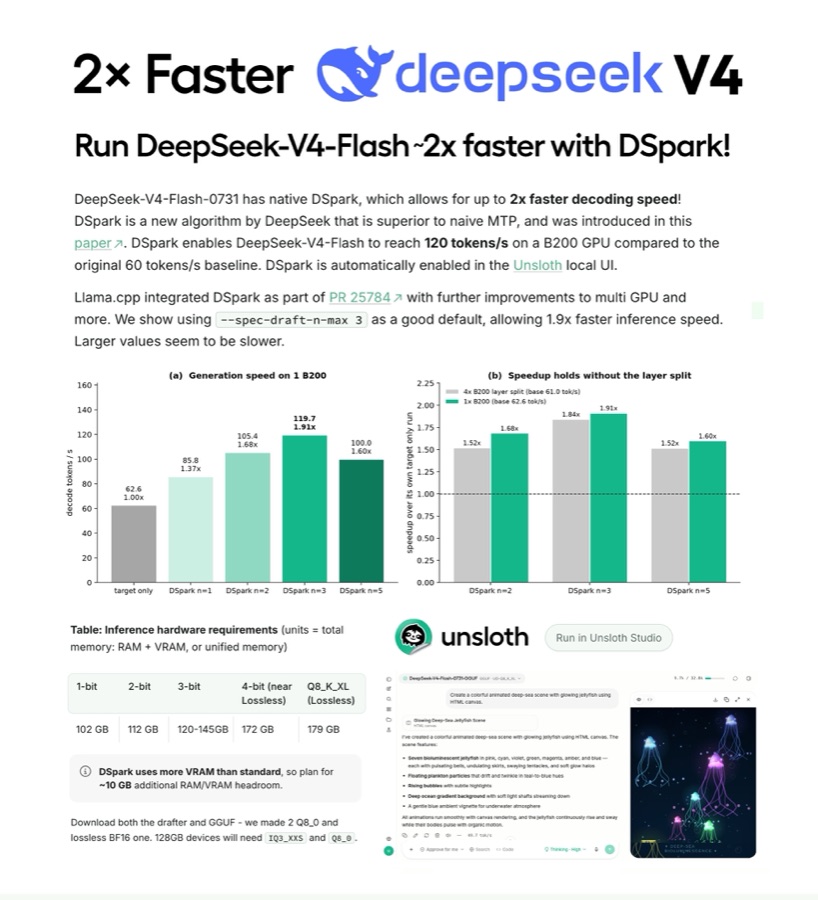
The Same DeepSeek, 2x Faster: What DSpark Changes
It combines Unsloth's Dynamic GGUF quantization with acceleration. It optimizes the inference pipeline while keeping the model's quantized state, so speed goes up and quality stays the same. It also enables MTP (multi-token prediction) automatically to raise decoding speed further.
Why V4 Flash Stands Out Locally: It's Not Just Speed
- Scale: 284B total parameters, 13B active per token (MoE)
- Context: up to 1 million tokens
- Performance: 82.7% on Terminal Bench 2.1, beating the same-size V4-Pro (preview)
Which Version Fits My GPU? How to Choose a Quantization
| Version | Size | Quality |
|---|---|---|
| UD-Q8_K_XL | 162GB | Fully lossless: bit-for-bit identical to the official weights |
| UD-Q4_K_XL | 155GB | Near-lossless: only non-expert tensors kept at Q8 |
| UD-IQ3_XXS | 103GB | Recommended: balance of quality and size |
| 1-bit / 2-bit | 92GB / 102GB | Smallest size |
All of them need a lot of RAM/VRAM, starting at 92GB, and the recommended 103GB version needs 110GB or more. This assumes a workstation or server-class setup, not most personal PCs.
One More Check Before Installing: What the Benchmarks Don't Say
1. You need the latest llama.cpp. Without the latest PR, the Q8 GGUF gives wrong results.
2. RAM is the main bottleneck. With a large context, you may need 110GB to 135GB.
3. There are reports that initial generation is slow, at 7 to 8 t/s, on a 2x RTX 3090 community quantization.
One Way to Lower Local Inference Costs, and Something More Important Than Speed
The open-weights camp is widening competition from model performance to operating efficiency. Techniques that run the same model faster and with fewer resources are the key to lowering the cost of running AI locally. If you already have the hardware, this update is worth trying right away.
Related: Unsloth release · Hugging Face · X post