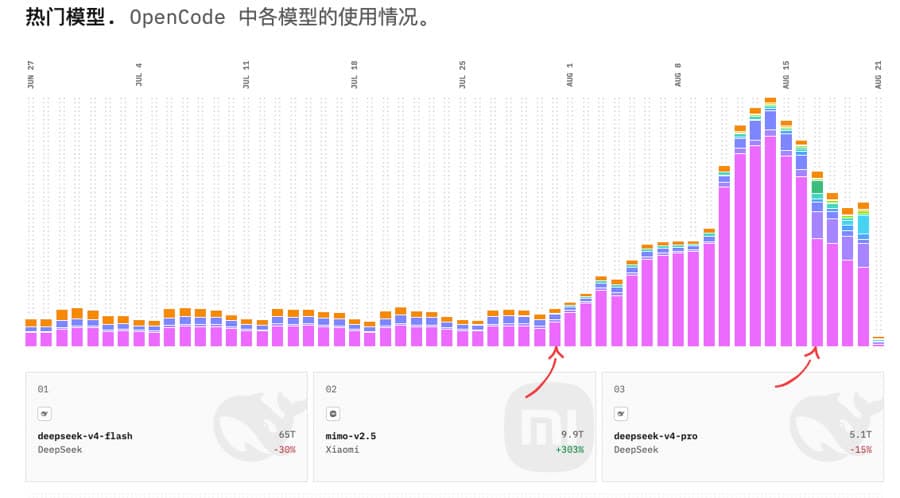
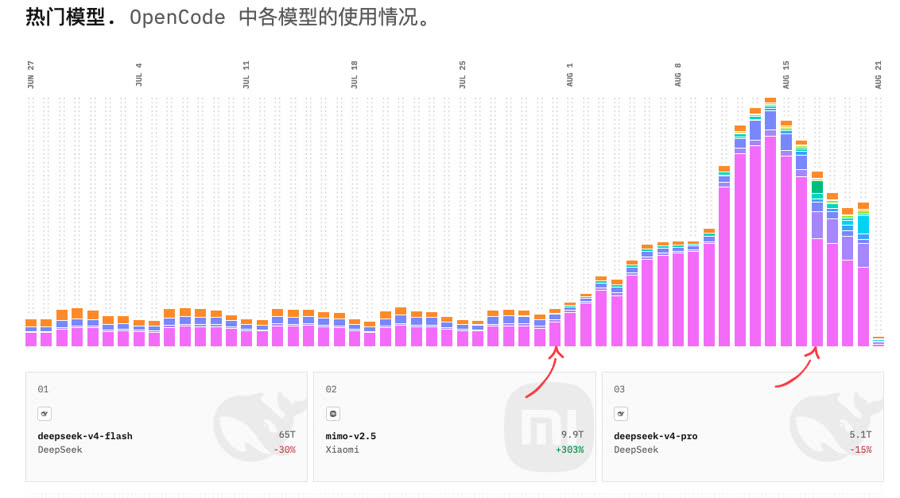
Jay (@jayair), CEO of the coding agent platform OpenCode, shared DeepSeek V4 Flash's usage trend directly at 9:26 a.m. KST on August 21, 2026. According to the post, which drew more than 170,000 views, the model launched on August 1 and within two weeks its daily throughput on OpenCode grew 6x, from 3 trillion tokens to 18 trillion tokens. Jay said that increase is close to the total daily throughput of all of OpenRouter.
Why it grew so explosively
Jay said it was because the model was unusually cheap. By the multiples he shared, it was 350x cheaper than Fable, 175x cheaper than GPT-5.6 Sol, 70x cheaper than Sonnet, and 7x cheaper than Luna. He added that performance also improved clearly over the previous-generation Flash model. Jay called it "the moment users first felt AI that is too cheap to meter."
August 16: a price hike stopped the growth
But on August 16, DeepSeek raised peak-hour rates 5x and off-peak rates 2.5x, and the growth stopped cold. According to Jay, throughput is now less than half its peak. The price hike itself was already reported separately: a pricing overhaul that took effect at 1 a.m. KST on August 17 with increases of up to 1,100%.
Jay's guesses at the cause were that DeepSeek may not have been able to handle the 6x jump in demand, and that rising GPU costs may have made it hard to secure new capacity at the old price. He said the OpenCode team spent the past week looking for other providers that could serve DeepSeek Flash at the original price level, but very few had the capacity to fill a gap of 10 trillion tokens a day. Covering it would take about 1,000 B300 GPUs on the latest hardware, he said.
What this means in practice
This case shows that piling workloads onto an ultra-cheap open model leaves you fully exposed to the provider's pricing changes. If your development team relies on a particular low-cost model to save money, you need a multi-vendor strategy with alternative providers or fallback models lined up in advance. On the other hand, this gap is an opportunity for other labs that can offer a model in a similar price and performance range.
What still needs confirmation
The figures, from 3 trillion to 18 trillion tokens and then a drop to less than half, all come from OpenCode's own tallies and have not been announced by DeepSeek or independently verified by a third party. The estimate that "1,000 B300s would be needed" is also Jay's own calculation, and its basis has not been published beyond the original tweet.